
Firecrawl is an open-source web data API that lets AI agents search, scrape, crawl, map, and interact with live web pages, returning clean Markdown or JSON ready for LLMs.
About
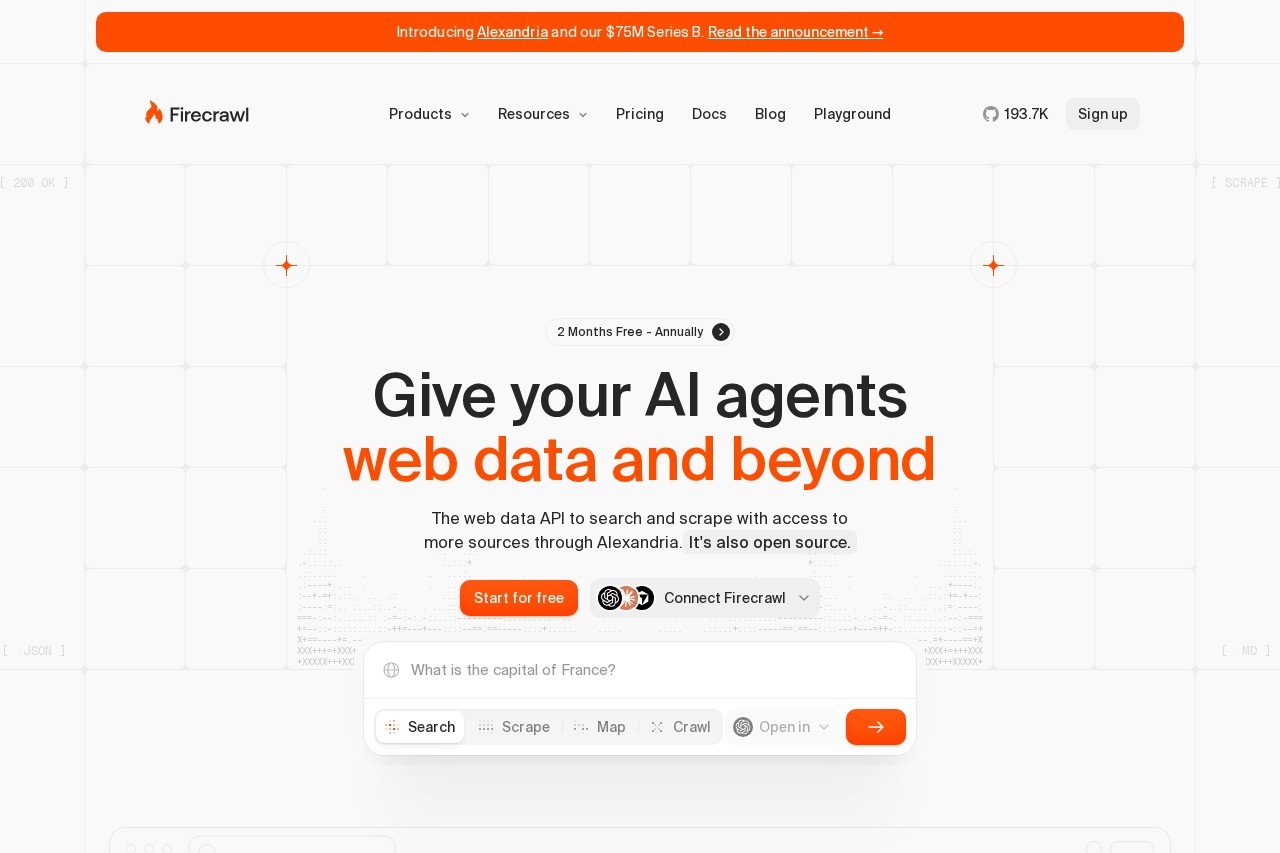
Firecrawl is a web data API built for AI agents and LLM applications. It addresses a common bottleneck in AI development: language models need clean, current web content, but raw HTML is noisy, token-heavy, and difficult to use directly. Firecrawl handles the fetching, rendering, and cleaning so developers receive Markdown or structured JSON that a model can consume without extra processing.
The service covers a full workflow in a single API family: find information with Search, extract pages with Scrape, traverse whole sites with Crawl, discover site structure with Map, parse documents with Parse, drive real browsers with Interact, and track changes with Monitor. It is a managed service that does not require a local browser setup, and the core codebase is open source on GitHub, where it had roughly 194,000 stars. The company also offers Firecrawl Alexandria, a licensed content source layered on top of live web access.
Key Features
Pricing & Fees
- Pricing: A free tier gives 1,000 credits per month with no card required. Paid plans, billed annually: Hobby $16/month (5,000 credits), Standard $83/month (100,000 credits), Growth $333/month (500,000 credits), and Scale $599/month (1,000,000 credits); Enterprise pricing is custom. Prices are USD and effective September 4, 2026.
- Credit system: One credit covers one page on a basic scrape, crawl, or map; search costs 2 credits per 10 results; Interact costs 2 credits per browser minute.
- Performance claims: The vendor reports 96% coverage on its own 1,000-URL benchmark (run January 13, 2026) versus 79% for Puppeteer and 75% for cURL, with a P95 latency of 3,387 ms and about 93% fewer input tokens versus raw pages.
- Open source: The codebase is public on GitHub and can be self-hosted.
- Not charged for empty results: A scrape that returns no result is not billed, though error-status pages such as 404 still cost one credit.
Who It's For
Firecrawl is aimed at developers building AI agents, chatbots, and research tools that need live web context. Typical users include AI application engineers wiring retrieval into assistants, data teams building crawling pipelines, and builders using coding agents such as Claude Code or Cursor who want web access without writing scraper code. It also suits product teams that need document parsing, scheduled page monitoring, or licensed content access through Alexandria for research and knowledge applications.
FAQ
What is Firecrawl?Firecrawl is an open-source web data API that lets AI applications search, scrape, crawl, map, parse, and interact with web pages, returning clean Markdown or JSON optimized for language models.
Is there a free plan?Yes. The free tier provides 1,000 credits per month (about 500 searches or 1,000 scraped pages) with two concurrent requests and no credit card required.
What platforms and integrations does Firecrawl support?It offers official SDKs for Python, Node.js, and Go, a CLI, an MCP server for clients such as Claude, Cursor, and VS Code, and pre-built agent skills; Scale and Enterprise plans are also available through AWS and Google Cloud marketplaces.
How does Firecrawl compare to running Puppeteer or cURL directly?On Firecrawl's own 1,000-URL benchmark it reported 96% successful coverage versus 79% for Puppeteer and 75% for cURL, while also handling JavaScript rendering, smart waits, and content cleaning automatically.
Can Firecrawl be self-hosted?Yes. The codebase is open source on GitHub, so teams can inspect it, contribute, or run it themselves, and Enterprise plans add options such as zero-data retention and SSO.
Related Tutorials
View all →

Related Tools
View all → TinyFish TinyFish is web infrastructure for AI agents that combines live web search, page fetching, cloud browser sessions, and multi-step automation behind a single API.
 OmniRoute - Free AI Gateway for Multi-Provider LLMs Free, open-source AI router with auto-fallback. 236 providers, one endpoint, 95 MCP tools, 17 routing strategies, A2A protocol, auto-combo engine, semantic cache, memory & skills. Deploy anywhere.
 OpenHands Open-source, model-agnostic platform for building and deploying cloud coding agents. Automate real engineering work securely with full transparency and control.
 Agent-Native Apps Framework Build agentic apps where AI agents and UI share the same database and state. Open source framework with ready-to-fork templates.
 DeerFlow - Agent Framework A LangChain-based framework for building super agents. Streamlines the development of advanced AI agents with ease.