
MiniMind enables training large language models from scratch, offering comprehensive resources and tools.
About
Welcome to MiniMind! This is a hands-on guide and resource platform dedicated to training large language models from scratch. As the AI wave continues to reshape the technology landscape, understanding the core process of building large language models has become essential for developers, researchers, and tech enthusiasts alike. MiniMind is designed to offer you a clear and practical path—taking you from theory to practice so you can build your very own language model with your own hands.
Key Features
Pricing & Fees
- Pricing: Not publicly listed on the pages we reviewed; check the official site for current plans.
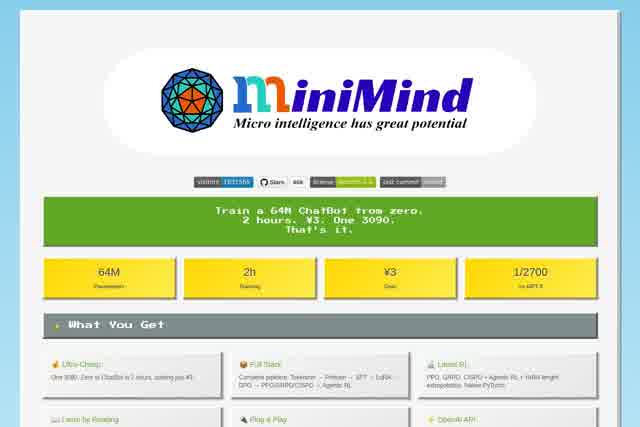
- Training Cost: Training the 64M model from scratch takes about 2 hours on a single RTX 3090, at an estimated cost of around ¥3.
- Free & Open Source: The code and models are provided openly, including MiniMind-3 (64M Dense) and MiniMind-3-MoE (198M/A64M), with pure PyTorch implementations.
- Hardware Requirements: The 64M model needs roughly 0.5 GB of memory, and the MoE variant about 1.0 GB, keeping hardware costs minimal.
- Compatibility: Supports vLLM, ollama, llama.cpp, SGLang and transformers, and offers an OpenAI-compatible API that works with FastGPT, Open-WebUI and Dify.
Who It's For
MiniMind is for AI beginners who are curious about the underlying principles of large language models, as well as machine learning engineers and researchers who want to deepen their understanding of the full training process to improve their development skills. It's also ideal for students and academics looking to put large model training into practice in course projects or research, and for any tech enthusiast who aspires to move from being a user to a creator.
Related Tutorials
View all →
