PaddleOCR: The Ultimate Document Solution
A powerful OCR tool for accurate text extraction from documents and images.
Introduction
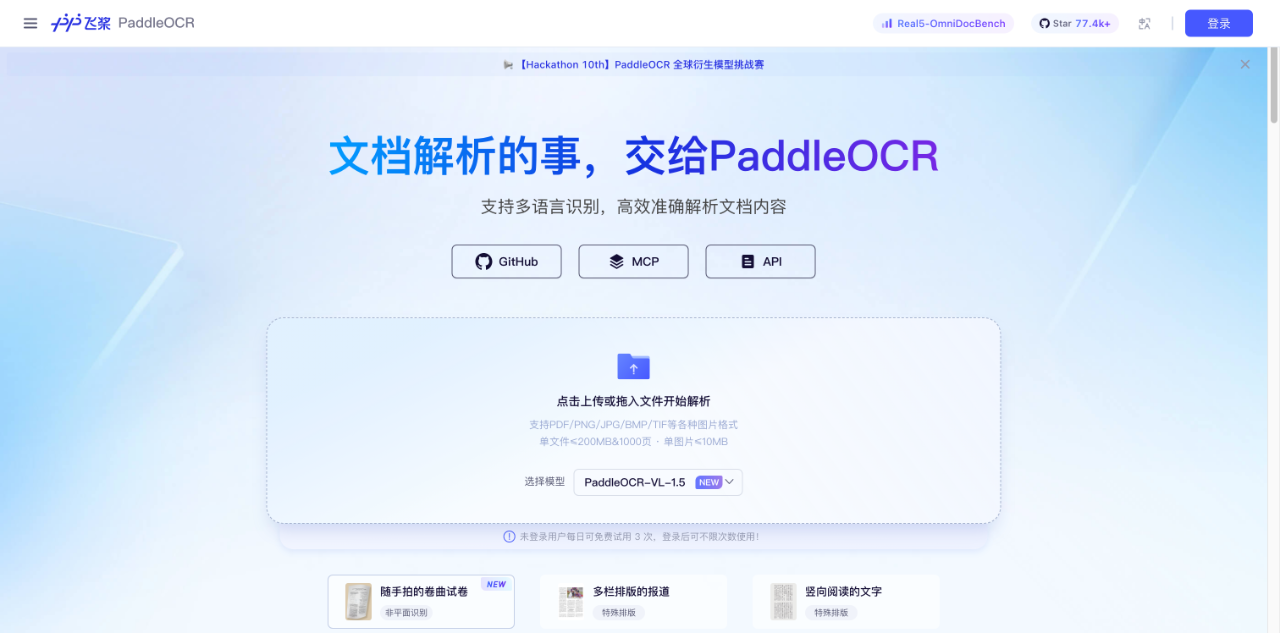
PaddleOCR is an end-to-end optical character recognition toolkit developed by Baidu PaddlePaddle, designed to deliver efficient and accurate document intelligence solutions for both enterprises and individuals. Whether dealing with printed text, handwriting, or text in complex real-world scenes, PaddleOCR completes the entire pipeline from image preprocessing to text output with extremely low latency. The toolkit supports recognition across multiple languages and offers robust layout analysis and structured output capabilities, making it one of the most popular open-source OCR projects in the industry today.
Key Features
- Multilingual Recognition: Supports text recognition in over 80 languages, including Chinese, English, Japanese, and Korean, covering major global languages.
- Layout Analysis: Automatically identifies document structures such as paragraphs, tables, headings, headers, and footers while preserving the original reading order.
- Handwriting Recognition: Specially optimized for natural handwritten text, achieving an accuracy rate of over 95%.
- Table Reconstruction: Extracts table data from images or PDFs and outputs directly to Excel or HTML formats.
- Lightweight Models: Offers a range of models from ultra-lightweight to high-precision, supporting flexible deployment on both mobile and server environments.
Highlights
- Out-of-the-Box Experience: Provides pretrained models and one-click deployment scripts, enabling rapid adoption without requiring large amounts of labeled data.
- High Accuracy and Speed: Achieves leading recognition accuracy on public benchmarks while maintaining millisecond-level inference speed.
- Complete Pipeline Coverage: Integrates text detection, orientation classification, and text recognition into a single toolkit with no need for additional assembly.
- Active Community: With over 40k GitHub stars and comprehensive documentation, users can quickly get support from the community when encountering issues.
- Free and Open Source: Licensed under Apache 2.0, allowing free use in commercial projects without licensing risks.
Who It's For
PaddleOCR is designed for a broad range of users. Enterprise developers can quickly integrate OCR capabilities into financial, archival, and contract management systems. Data annotation teams can leverage OCR to preprocess large volumes of images and reduce manual data entry costs. Academic researchers can use it to study text detection and recognition algorithms, or to process special documents such as ancient books and manuscripts. Individual enthusiasts who want to digitize paper notes, business cards, or books will also find it an accessible and practical tool.