
Transform PDFs into Markdown or JSON for LLM use. 100% local, open-source under Apache-2.0.
About
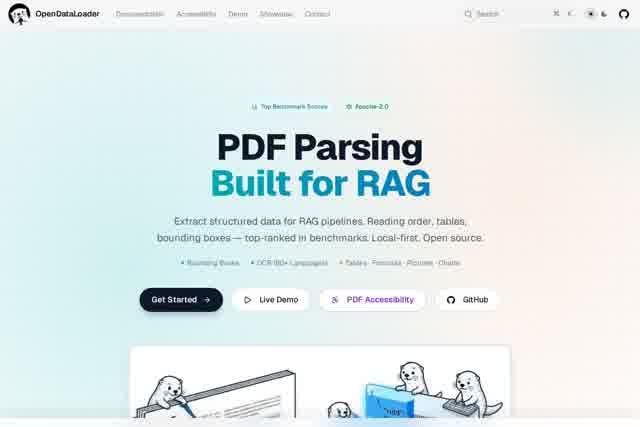
As artificial intelligence and large language models (LLMs) continue to evolve rapidly, structured parsing of PDF documents has become a critical step in data preparation. OpenDataLoader PDF is a local, open-source PDF parser built specifically for AI data readiness, efficiently converting PDF files into LLM-ready Markdown and JSON formats. The tool supports bounding box references and automatically converts untagged PDFs into tagged PDFs, ensuring compliance with accessibility standards. Licensed under Apache-2.0, OpenDataLoader PDF runs entirely on your local machine with no dependency on cloud services, safeguarding data security and privacy.
Key Features
Pricing & Fees
- Pricing: OpenDataLoader PDF is free and open source under the Apache-2.0 license, with no paid plans listed on the official site.
- Free & self-hosted: Runs 100% locally with no GPU required, processing about 20+ pages per second on CPU, so there are no per-page or API usage costs.
- SDK availability: Official SDKs for Python, Node.js, and Java can be installed from standard package managers such as pip and npm.
- Optional hybrid mode: An optional LLM-enhanced mode improves OCR and complex table extraction (93% table accuracy in benchmarks), which may incur third-party LLM API costs.
Who It's For
OpenDataLoader PDF is designed for AI engineers and data scientists who need to rapidly convert large volumes of PDF documents into training data for building RAG systems or fine-tuning LLMs. It is also ideal for document processing developers who want to integrate PDF parsing into local applications with strict data privacy requirements, accessibility compliance specialists responsible for converting untagged PDFs into accessible formats, and academic researchers who need to extract structured data from papers and reports for bibliometric analysis or knowledge discovery.
Related Tutorials
View all →
Related Tools
View all → n8n MCP - AI Workflow Automation Connect AI to n8n workflows with MCP. Use Claude, Cursor, and 20+ AI tools to automate tasks.
 MemPalace - AI Memory Palace MemPalace is an AI-powered memory palace that helps you organize and recall information using MCP.
 Desktop Commander - AI That Executes Desktop Commander reads your files, runs commands, and automates workflows - all in natural language.
 FastGPT FastGPT is a powerful AI knowledge base platform that combines RAG, AI workflows, and MCP support to build intelligent assistants and automate tasks.
 Activepieces Activepieces is an automation platform that empowers teams to create AI-powered workflows without coding, bridging IT and business needs.