
Crawl4AI is a web crawler designed for LLM applications. It efficiently extracts and structures data for AI training and analysis.
About
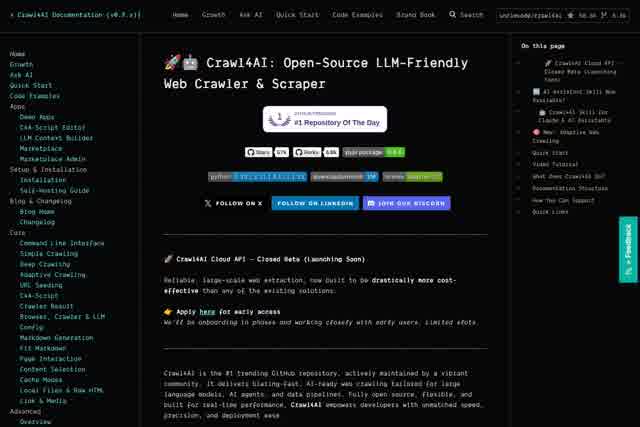
Crawl4AI is an open-source web crawler and data extraction tool purpose-built for large language model (LLM) applications. It tackles the common pain points of traditional scraping tools, such as inefficient data cleaning, unstructured output, and poor compatibility with AI pipelines. With a clean API design and a powerful parsing engine, Crawl4AI quickly transforms any webpage into clean text or structured data that LLMs can consume directly. It helps developers, data scientists, and AI researchers dramatically improve the speed and quality of data acquisition and preprocessing.
Key Features
Pricing & Fees
- Pricing: Hosted API plans start at $10/month (Starter: 10,000 credits, 120 requests/minute, 10 concurrent), with Builder at $99 and Scale at $499 per month; the self-hosted open-source version is free.
- Free tier: A free API key includes 1,000 credits per month, at 10 requests per minute and 2 concurrent requests.
- Credits: Extra credits purchased on a paid plan never expire; a live price table is available via the /v1/prices endpoint.
- License: The open-source crawler is licensed under Apache-2.0 (older releases under MIT) with no commercial restrictions.
- API access: One key works across /scrape, /extract, /search, /serp, and /answer endpoints, plus MCP integration with Claude Code, Codex, Cursor, and other agents, served from EU, Singapore, and US regions.
Who It's For
Crawl4AI is especially well-suited for AI and LLM developers who need large volumes of clean, structured web data for model training, fine-tuning, or knowledge base construction. It also serves data scientists and analysts who want to quickly aggregate information from multiple websites for trend analysis or competitive research, as well as researchers extracting text data from academic sites, news portals, or social media. Additionally, automation engineers and content operations teams can use it to monitor webpage updates, scrape product information, or aggregate industry news on a regular basis.
Related Tutorials
View all →
Related Tools
View all → AI Tool - AI-Powered Solutions This AI tool provides intelligent solutions to streamline workflows, enhance productivity, and deliver accurate results across various tasks.
 LiblibAI 2.0 An advanced AI platform offering powerful tools for image generation, editing, and creative workflows.
 Seedance 2.0 - AI Video Generator Create stunning AI-generated videos with Seedance 2.0. Turn text into dynamic visuals effortlessly.
 AI Image Generator - AI Art Creation Create stunning AI art with this tool, similar to Midjourney but with 2.5x faster generation. It offers advanced features for generating high-quality images from text prompts.
 OpenRouter OpenRouter is a unified, OpenAI-compatible API that gives developers pay-as-you-go access to 500+ AI models for text, image, video, and audio from 80+ providers.