TensorRT-LLM
TensorRT-LLM is NVIDIA's high-performance inference library for LLMs, delivering low latency and high throughput.
Introduction
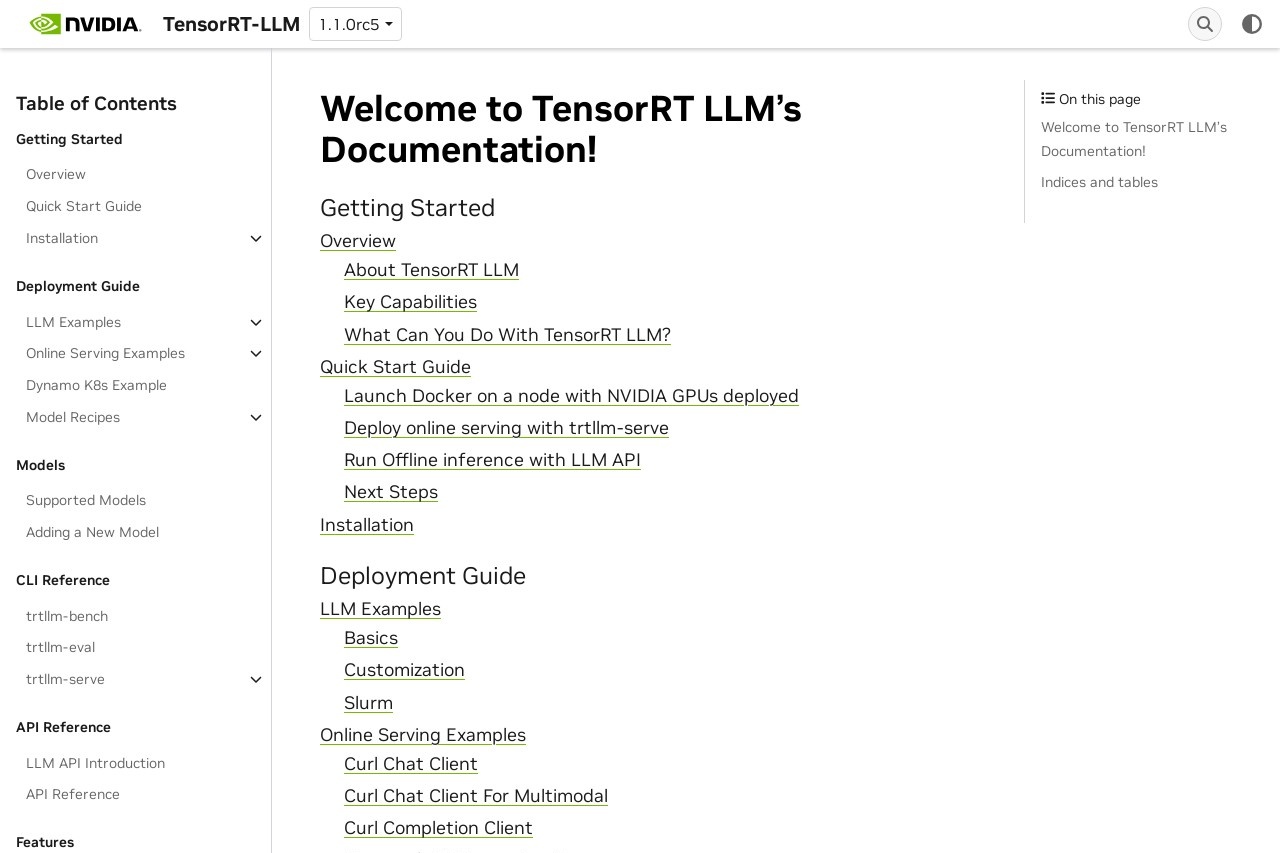
TensorRT-LLM is a high-performance deep learning inference library developed by NVIDIA, purpose-built for large language models (LLMs). Built on top of NVIDIA TensorRT, it is designed to help developers and enterprises efficiently deploy and run large-scale language models, significantly boosting inference speed and resource utilization. Whether applied to natural language processing, conversational AI, or content generation, TensorRT-LLM delivers robust tools and comprehensive support.
Key Features
- High-performance inference optimization: Dramatically accelerates model inference through kernel fusion, quantization techniques, and dynamic shape support.
- Multi-GPU scaling: Supports parallel inference across multiple GPUs, making it easy to handle deployment of extremely large models.
- Framework compatibility: Seamlessly integrates with mainstream deep learning frameworks such as PyTorch and TensorFlow.
- Detailed documentation and examples: Provides extensive developer guides, API references, and code samples to lower the barrier to entry.
Highlights
- Core strength lies in extreme performance optimization combined with ease of use.
- Fully leverages NVIDIA hardware (such as GPUs) through intelligent memory management and computation graph optimization, achieving low-latency, high-throughput inference.
- An open development environment and comprehensive technical support make the journey from research to production deployment smoother.
Who It's For
TensorRT-LLM is well suited for a wide range of scenarios and user groups, including AI researchers, machine learning engineers, DevOps engineers, and technical decision-makers in enterprises. Whether you are a startup looking to accelerate model inference or a large organization needing to deploy massive language models, TensorRT-LLM offers tangible benefits.