oMLX - LLM Inference Optimized for Mac
A native macOS inference server on MLX with paged SSD KV caching, reducing TTFT to under 5s. OpenAI & Anthropic compatible.
Introduction
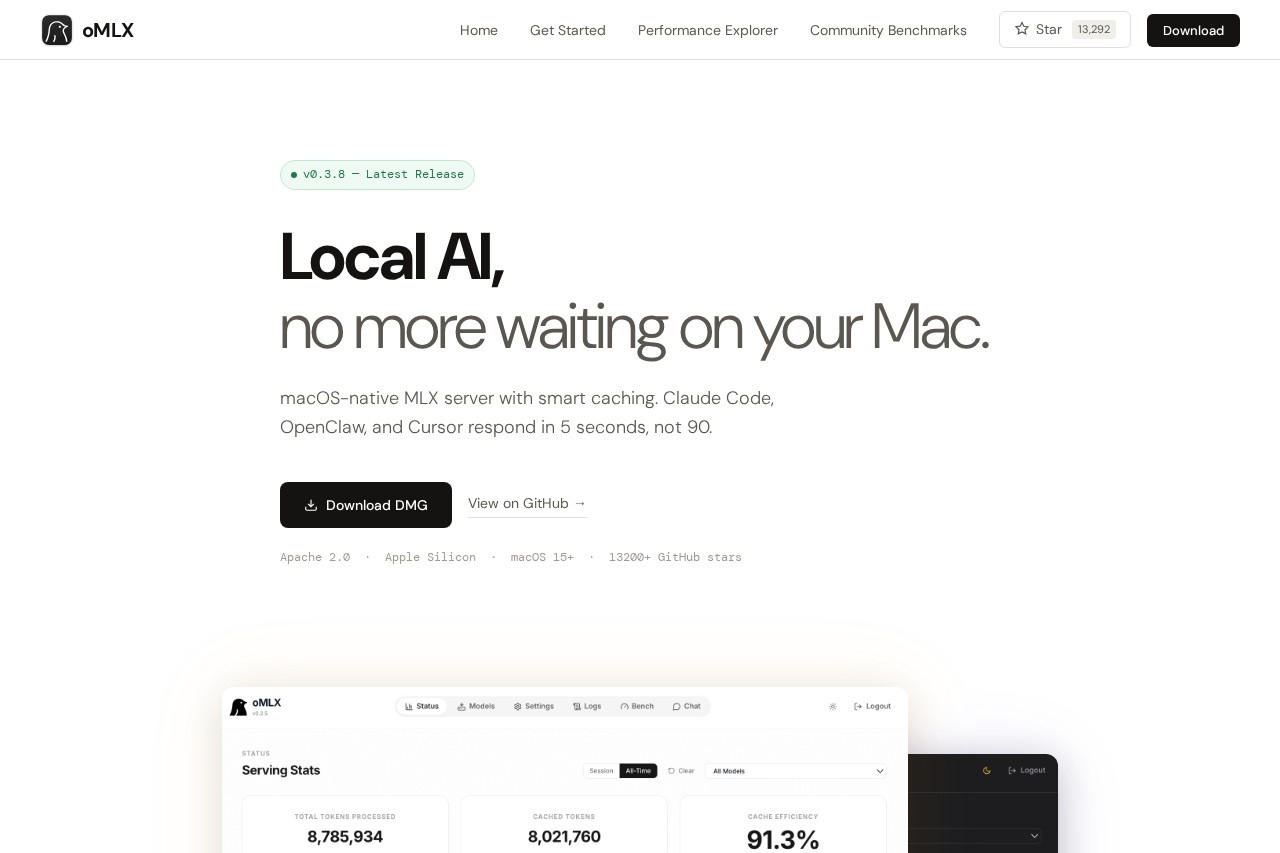
oMLX is a native inference server designed specifically for macOS, built on Apple's MLX framework to fully unlock the deep learning potential of Apple Silicon chips. Whether you're running large language models (LLMs) or building intelligent agent applications, oMLX delivers efficient, low-latency local inference. With its innovative Paged SSD KV caching technology, oMLX dramatically reduces the time-to-first-token (TTFT) for agent tasks from the traditional 30-90 seconds down to under 5 seconds, making local AI applications truly ready to use out of the box. Additionally, oMLX offers API interfaces compatible with both OpenAI and Anthropic, allowing developers to seamlessly migrate existing projects with minimal effort.
Key Features
- Native macOS inference engine: Deeply optimized for Apple Silicon's unified memory architecture, supporting M1/M2/M3 series chips without requiring additional GPUs or accelerator cards.
- Paged SSD KV caching: Breaks through memory limits by paging key-value caches to SSD during long-context inference, significantly reducing first-token latency for multi-turn conversations and complex agent scenarios.
- OpenAI / Anthropic compatible API: Provides standard RESTful endpoints including Chat Completions and Embeddings, allowing you to switch to local models with a single line of code.
- Hot loading and model management: Supports dynamic loading and unloading of models without restarting the service, making it easy to test different quantized versions or fine-tuned models.
- Lightweight deployment: A single binary file with no complex dependencies, installable in minutes via Homebrew or manual download.
Highlights
- Ultra-fast first-token response: Paged SSD caching reduces wait times for agent-style applications (such as code assistants and multi-step reasoning) from minutes to seconds, greatly improving user experience.
- Complete local privacy: All inference runs locally with no data leaving your device, ideal for handling sensitive information or offline environments.
- Zero-configuration compatibility: Connect to oMLX directly using the OpenAI SDK or Anthropic SDK without modifying existing code logic, lowering migration costs.
- Efficient resource utilization: Instruction-level optimization for Apple Silicon's Metal backend delivers higher throughput at the same power draw, extending MacBook battery life.
- Active community and documentation: Open-source project with detailed configuration guides, performance benchmarks, and FAQs, continuously updated to support the latest model architectures.
Who It's For
AI application developers who need to quickly build local LLM-powered tools (such as intelligent customer service, document analysis, or code generation) while keeping inference costs and latency under control. Privacy-conscious users in enterprise or individual settings who handle medical, legal, or financial data and require all inference to run locally to avoid cloud transmission risks. macOS performance enthusiasts who want to fully leverage Apple Silicon hardware to run mainstream open-source models (such as LLaMA, Mistral, and Phi) locally. Researchers and prototyping teams who need to rapidly validate multi-turn conversations or agent workflows without being constrained by cloud API rate limits or network instability.