NVIDIA Dynamo
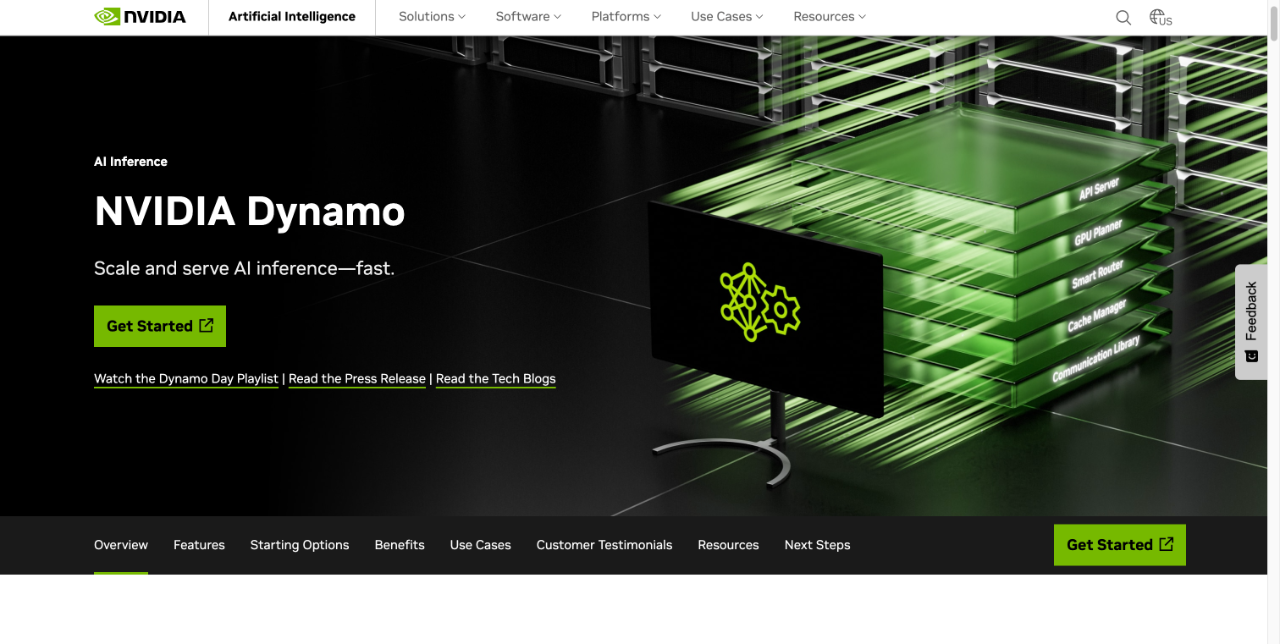
NVIDIA Dynamo accelerates AI inference with high-performance infrastructure, ensuring low latency and scalability.
Introduction
NVIDIA Dynamo is an open-source, modular inference framework designed to efficiently serve generative AI models in distributed environments. It simplifies the deployment and management of large-scale AI models, helping developers and enterprises seamlessly integrate advanced generative AI capabilities into real-world applications.
Key Features
- Distributed inference serving: Runs generative AI models efficiently across multi-node, multi-GPU environments.
- Modular architecture: Lets users flexibly select and combine components such as model loaders, request schedulers, and post-processing modules.
- Dynamic scaling: Automatically adjusts resource allocation based on workload to ensure high availability and low latency.
- Multi-model support: Manages multiple model versions and types simultaneously, making A/B testing and model iteration straightforward.
Highlights
- High performance and ease of use are the core strengths of NVIDIA Dynamo.
- Deep integration with NVIDIA hardware acceleration technologies, including Tensor Core GPUs and NVLink, significantly boosts inference speed.
- Open-source nature enables continuous community contributions and optimizations.
- Modular design reduces the complexity of integration and customization.
- Built-in monitoring and logging features let users track service status in real time and quickly identify issues.
Who It's For
This framework is ideal for AI researchers, machine learning engineers, DevOps teams, and any organization that needs to deploy generative AI models in production. Whether you are building intelligent chatbots, content generation systems, or complex data analysis tools, NVIDIA Dynamo delivers reliable inference serving support.