
TensorRT-LLM is NVIDIA's high-performance inference library for LLMs, delivering low latency and high throughput.
About
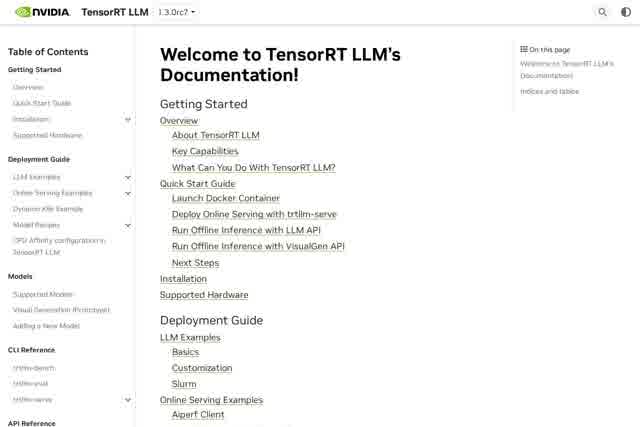
TensorRT-LLM is a high-performance deep learning inference library developed by NVIDIA, purpose-built for large language models (LLMs). Built on top of NVIDIA TensorRT, it is designed to help developers and enterprises efficiently deploy and run large-scale language models, significantly boosting inference speed and resource utilization. Whether applied to natural language processing, conversational AI, or content generation, TensorRT-LLM delivers robust tools and comprehensive support.
Key Features
Pricing & Fees
- Pricing: Not publicly listed on the pages we reviewed; check the official site for current plans.
- Licensing: TensorRT-LLM is an open-source library from NVIDIA with public documentation, so there is no per-seat fee for the software itself.
- Hardware requirements: It targets NVIDIA GPU hardware, and deployment guides cover specific architectures such as Blackwell and Hopper.
- Features: Supports optimized inference features including in-flight batching, speculative decoding, KV cache compression and offloading, and LoRA adapters.
- Serving options: Includes an OpenAI-compatible serving API (trtllm-serve) plus benchmarking and evaluation CLI tools.
Who It's For
TensorRT-LLM is well suited for a wide range of scenarios and user groups, including AI researchers, machine learning engineers, DevOps engineers, and technical decision-makers in enterprises. Whether you are a startup looking to accelerate model inference or a large organization needing to deploy massive language models, TensorRT-LLM offers tangible benefits.
Related Tutorials
View all →
Related Tools
View all → DFlash: Block Diffusion for Flash Speculative Decoding - Z Lab DFlash is a cutting-edge technology by Z Lab that accelerates large language model inference through block diffusion and speculative decoding, delivering up to 3x speedup without compromising quality.
 Rig - Build Powerful LLM Applications in Rust Rig: A Rust framework for building modular, scalable LLM applications. Features a unified LLM interface, Rust-native performance, and advanced AI workflow abstractions to streamline development.
 Supervision Supervision by Roboflow provides tools for computer vision projects.
 Dify.AI Dify.AI is an open-source platform for building agentic AI workflows, RAG knowledge pipelines, and LLM apps, deployable on cloud, in a VPC, or self-hosted with Docker.
 Flowise Flowise is a low-code platform for building AI agents and LLM applications, enabling rapid development and deployment of AI solutions.