Open-source LLM evaluation framework with 50+ plug-and-play metrics for AI agents, RAG, chatbots, and more.
About
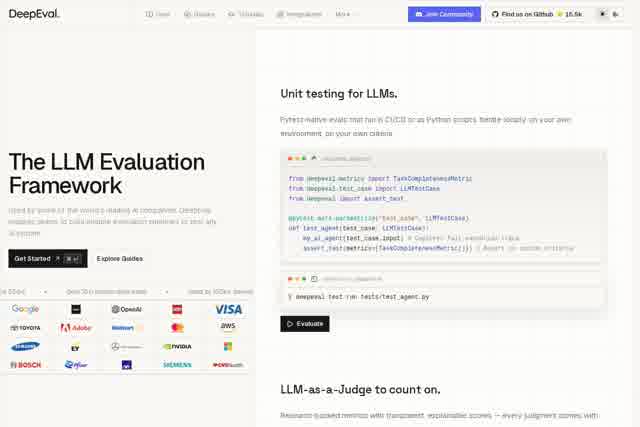
In modern AI application development, evaluating and testing large language models has become a critical factor in determining project success. DeepEval by Confident AI is an open-source LLM evaluation framework specifically designed for testing and benchmarking LLM applications. Whether you are building AI agents, RAG systems, chatbots, or other language model-based applications, DeepEval provides over 50 plug-and-play evaluation metrics to help development teams quickly and reliably measure the quality, accuracy, and safety of model outputs. As a lightweight yet powerful tool, DeepEval is committed to making LLM evaluation as simple, repeatable, and integrable as unit testing.
Key Features
Pricing & Fees
- Pricing: Not publicly listed on the pages we reviewed; check the official site for current plans.
- Open-source framework: DeepEval is an open-source project with publicly available code, so the core framework can be used at no cost.
- Self-hosted evaluation: Runs locally with a local backend storage option, giving teams control over where evaluation data and results are kept.
- CI/CD integration: Evaluation scripts follow a pytest unit-testing style and can run in CI/CD pipelines for continuous regression testing.
Who It's For
DeepEval is designed for all professionals involved in LLM application development and operations, including but not limited to: AI application developers who need to continuously validate model output quality during development to ensure functional correctness; machine learning engineers and data scientists who want to systematically compare the performance of different models, prompts, or retrieval strategies; QA and testing engineers seeking automated evaluation solutions to incorporate LLM behavior testing into standard test workflows; and product managers and technical leads who need objective metrics to drive product iteration decisions and monitor model performance after deployment.
Related Tutorials
View all →

Related Tools
View all → 智谱清言 (ChatGLM) 智谱清言 is a Chinese conversational AI assistant built on Zhipu AI's GLM large language model, combining chat, agents, and multimodal creation tools in one platform.
 Poe Poe is a multi-model AI chat platform from Quora that lets users chat with many AI assistants, compare responses, and build custom bots in one place.
 Claude Claude is an AI assistant made by Anthropic that answers questions, writes and edits text, analyzes documents, and helps with coding through natural conversation.
 Openclaw (clawdbot) - Personal AI Assistant Moltbot-powered personal AI assistant that automates tasks and enhances productivity.
 Gemini Google's AI assistant that helps with writing, planning, brainstorming, learning, and coding, available on the web and mobile through a Google account.