Cactus - On-device AI for Smartphones, Laptops & Edge
One inference engine for on-device AI across smartphones, laptops, and edge hardware. Run LLMs, transcription, and embeddings locally with automatic cloud fallback.
Introduction
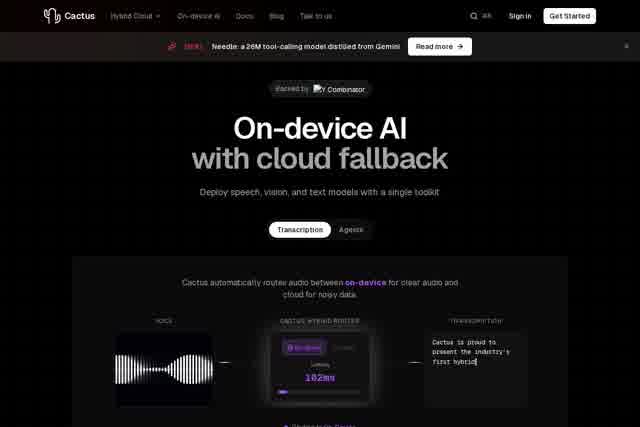
Cactus is a local AI engine built for smartphones, laptops, and edge hardware. It provides a unified inference runtime that lets developers run large language models (LLMs), speech transcription, and text embeddings directly on end-user devices. The core strength of Cactus lies in moving AI processing from the cloud to the local device, ensuring data privacy while delivering millisecond-level response times. When on-device compute is insufficient, it automatically falls back to the cloud, guaranteeing uninterrupted service.
Key Features
- Multi-model support: Seamlessly runs popular open-source LLMs (such as Llama and Mistral), Whisper speech transcription models, and a variety of embedding models.
- Automatic cloud fallback: When local device compute is insufficient or a specific model is not installed, inference requests are automatically forwarded to the cloud with no perceptible switch for the user.
- Cross-platform unified API: A single inference interface covers Android, iOS, Windows, macOS, and Linux edge devices, significantly reducing integration costs.
- Lightweight deployment: The core engine is only a few MB in size and supports dynamic model loading and caching, without consuming excessive storage.
- Offline-first: All inference tasks run locally by default, and basic AI functionality works without any network connection.
Highlights
- Zero privacy leakage: User data stays on the device at all times and never passes through external servers, making it suitable for sensitive industries such as healthcare and finance.
- Ultra-low latency: Local inference eliminates network round-trip delays, delivering response speeds 5-10x faster than pure cloud solutions.
- Cost control: Reduces cloud API call volume and significantly lowers operational costs, especially for high-frequency usage scenarios.
- Elastic architecture: Developers can dynamically adjust model precision (FP16/INT8/INT4) based on device GPU/NPU capabilities to balance speed and accuracy.
- Out-of-the-box experience: Precompiled SDKs and detailed documentation allow integration testing on mainstream devices within 10 minutes.
Who It's For
Cactus is designed for mobile app developers looking to integrate intelligent chat, real-time translation, or voice assistant features into their apps; edge computing engineers who need to run AI inference on low-power devices such as IoT gateways and industrial PCs; enterprise IT teams pursuing on-premise data processing while retaining the ability to scale elastically through the cloud; indie developers and startups that want to quickly validate AI product prototypes without incurring high initial cloud service costs; and academic researchers who need to test and fine-tune models on local hardware without depending on lab server clusters.