PageIndex - Human-like AI for Long Document Understanding
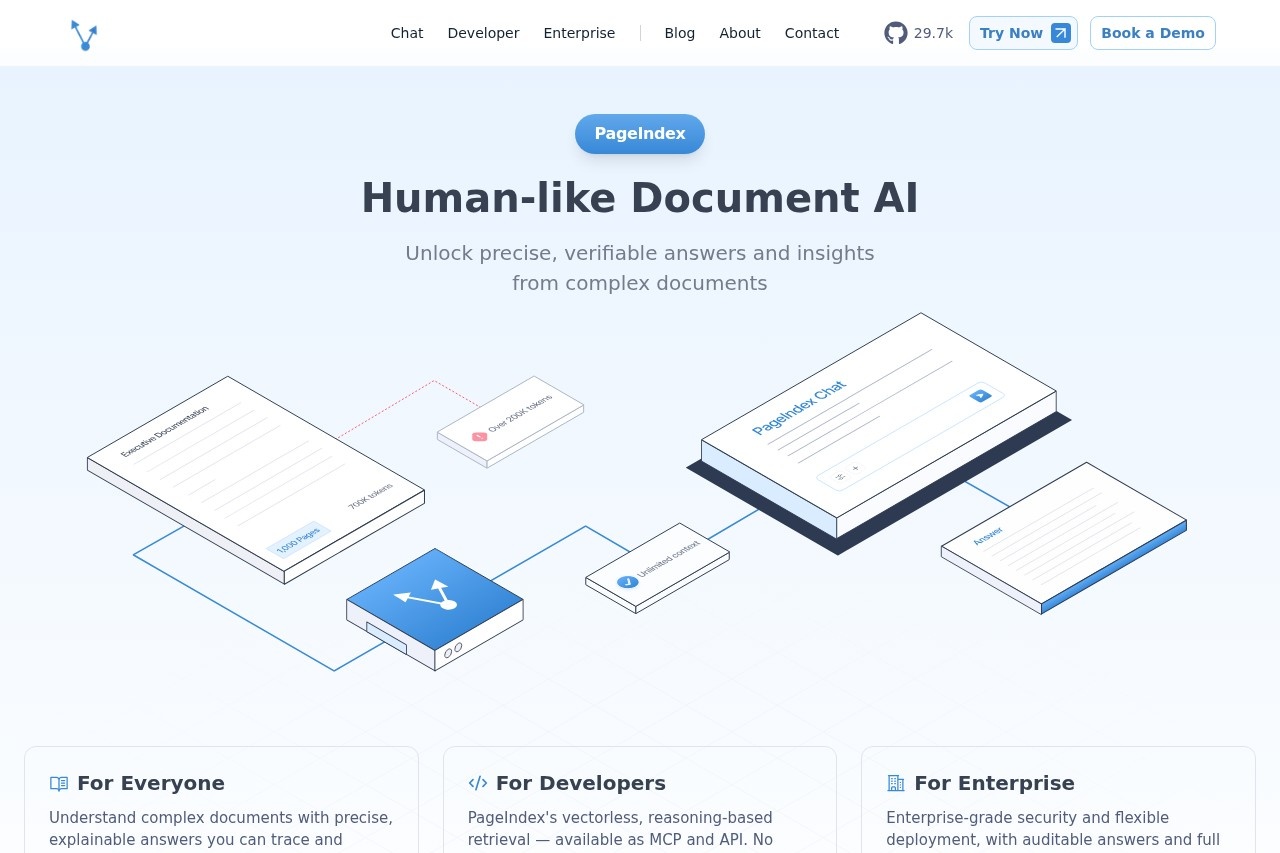
PageIndex is a vectorless, reasoning-based RAG engine that mirrors how humans read documents. Achieve 98.7% accuracy on FinanceBench with traceable, explainable retrieval.
Introduction
In an age of information overload, processing long documents—such as financial reports, legal contracts, or academic papers—often demands significant time and effort. Traditional retrieval-augmented generation (RAG) techniques can assist with comprehension, but they frequently rely on vector embeddings that break contextual connections, leading to fragmented and inaccurate answers. PageIndex was created to solve this problem. It is a groundbreaking vectorless, reasoning-based RAG engine designed to mirror the way humans read and understand documents. By following a unique "understand first, retrieve second" approach, PageIndex achieves 98.7% accuracy on the FinanceBench benchmark, delivering not only precise answers but also ensuring that every retrieval step is clearly traceable. This makes intelligent document understanding genuinely reliable and explainable.
Key Features
- Vectorless reasoning engine: Instead of traditional vector embeddings, PageIndex uses deep learning models to directly parse document structure and semantic logic, enabling human-like paragraph association and information location.
- Explainable retrieval paths: Every answer comes with a complete traceability chain, clearly showing the reasoning process from question to answer, allowing users to easily verify the authenticity of the information.
- High-precision long-document processing: Supports complex documents of hundreds of pages, maintaining contextual consistency across multi-table cross-references and long-passage reasoning without missing key information.
- Real-time interactive Q&A: Users can ask follow-up questions about any part of the document, and PageIndex dynamically adjusts its retrieval strategy to provide continuous, accurate responses.
Highlights
- Accuracy beyond tradition: Sets a new industry benchmark with 98.7% accuracy on demanding financial datasets like FinanceBench, with particular strength in handling numbers, dates, and conditional logic.
- Transparent and trustworthy: No more "black box" outputs. Every retrieval result includes source citations and reasoning steps, meeting the requirements of high-stakes scenarios such as audits and compliance.
- Extremely low resource consumption: No need to maintain large vector databases, significantly reducing deployment costs while improving query speed—ideal for enterprise-scale document management.
- Zero-friction integration: Offers a clean API interface and plugin support, allowing quick integration into existing knowledge bases, customer service systems, or internal workflow tools.
Who It's For
Financial analysts and auditors can quickly extract key data from prospectuses and financial statements while ensuring accurate citations, boosting the efficiency of due diligence and report writing. Legal and compliance professionals can precisely interpret contract clauses and regulatory documents with automatic cross-reference linking, reducing the risk of oversight in manual review. Researchers and academic editors can efficiently navigate paper reviews and experimental methods, using traceable retrieval to support literature analysis and peer review. Enterprise knowledge management teams can turn massive internal document repositories into intelligent Q&A systems, empowering employees with self-service search and reducing repetitive support work.