FunASR - End-to-End Speech Recognition Toolkit
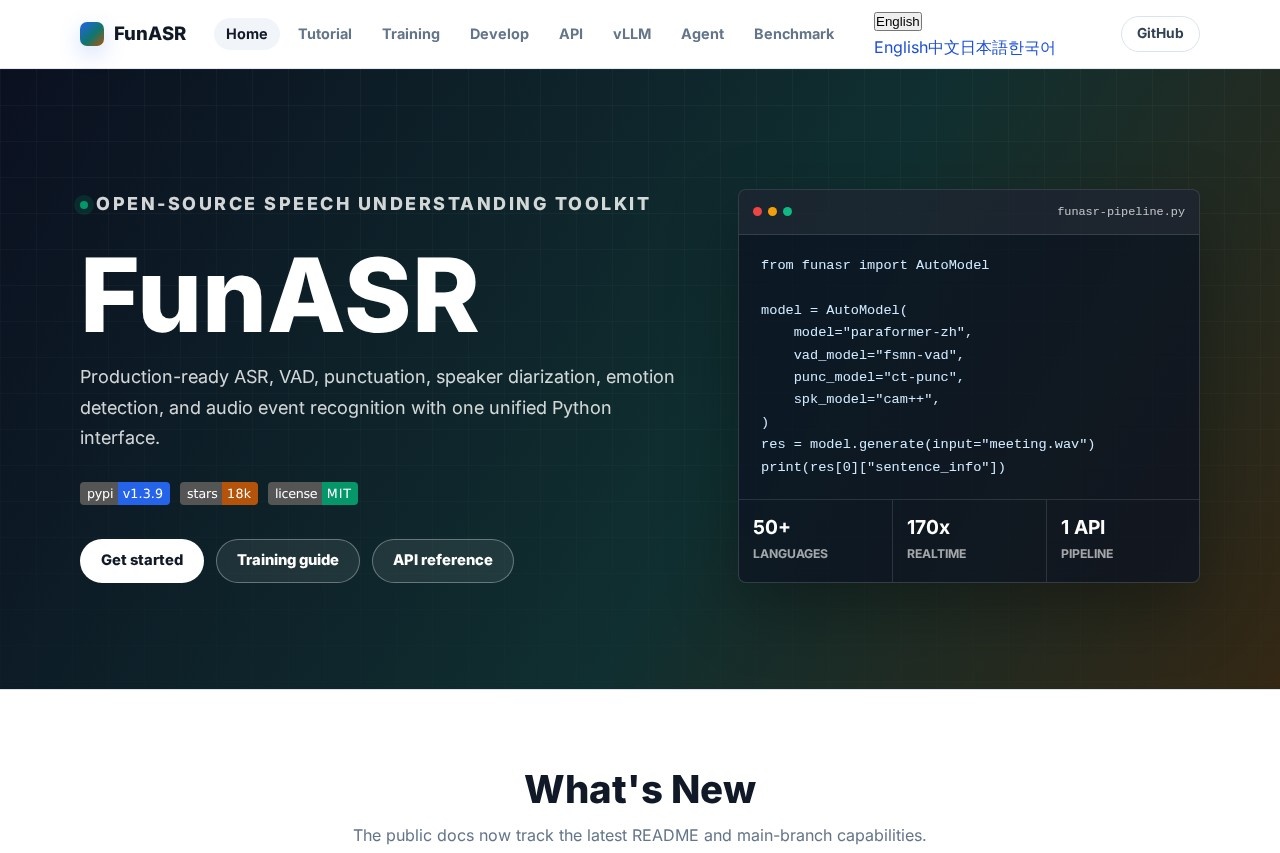
Industrial-grade speech recognition toolkit. 170x realtime on GPU, 50+ languages, speaker diarization, emotion detection, OpenAI-compatible API, vLLM acceleration, and agent integration.
Introduction
FunASR is an open-source end-to-end speech recognition toolkit designed for industrial-grade applications, developed and continuously maintained by the speech lab at Alibaba DAMO Academy. It integrates a complete set of speech processing capabilities, ranging from speech recognition and speaker diarization to emotion detection. The toolkit achieves inference speeds up to 170 times real-time on GPU and supports recognition in more than 50 languages. FunASR offers an OpenAI-compatible API interface and leverages vLLM acceleration to significantly boost large-model inference efficiency, enabling seamless integration into agent systems. It is an ideal choice for building high-accuracy, low-latency speech interaction applications.
Key Features
- High-precision speech recognition: Built on advanced self-supervised learning and end-to-end models, it maintains stable recognition accuracy across various noisy environments.
- Multi-language support: Covers more than 50 languages, including Chinese, English, Japanese, Korean, French, German, and selected dialects.
- Speaker diarization: Automatically distinguishes different speakers and outputs labeled conversation transcripts.
- Emotion detection: Analyzes emotional tone in speech in real time, supporting classification of common emotions such as anger, happiness, and sadness.
- Streaming and offline dual modes: Supports real-time streaming recognition as well as offline batch processing of full audio files, flexibly adapting to different business scenarios.
- Agent integration: Provides standardized interfaces for quickly embedding speech capabilities into intelligent customer service, voice assistants, and other agent systems.
Highlights
- Ultra-high performance: Achieves inference speeds up to 170 times real-time on NVIDIA GPUs, significantly reducing computational cost and latency.
- vLLM acceleration: Deeply optimized for large language models, notably improving decoding efficiency and suitable for large-scale concurrent deployment.
- OpenAI-compatible API: Offers a fully compatible interface with the Whisper API, allowing developers to replace existing services with zero migration cost.
- Industrial-grade stability: Proven in production environments within Alibaba and across numerous enterprise customers, supporting high concurrency and long-duration stable operation.
- Modular design: Each functional component is independent and pluggable, allowing users to flexibly combine features as needed and lowering the barrier for custom development.
Who It's For
FunASR is well suited for AI application developers who want to quickly add speech recognition, speaker diarization, or emotion analysis to their products while reducing self-development costs. It also serves enterprise technical teams that need to deploy high-concurrency, low-latency speech services for call centers, meeting transcription, live captioning, and similar scenarios. Developers working on agents and RPA solutions can integrate voice interaction into agent workflows for voice-driven automation. Academic researchers will find it a flexible, reproducible baseline system for speech technology experiments and comparisons.