DFlash: Block Diffusion for Flash Speculative Decoding - Z Lab
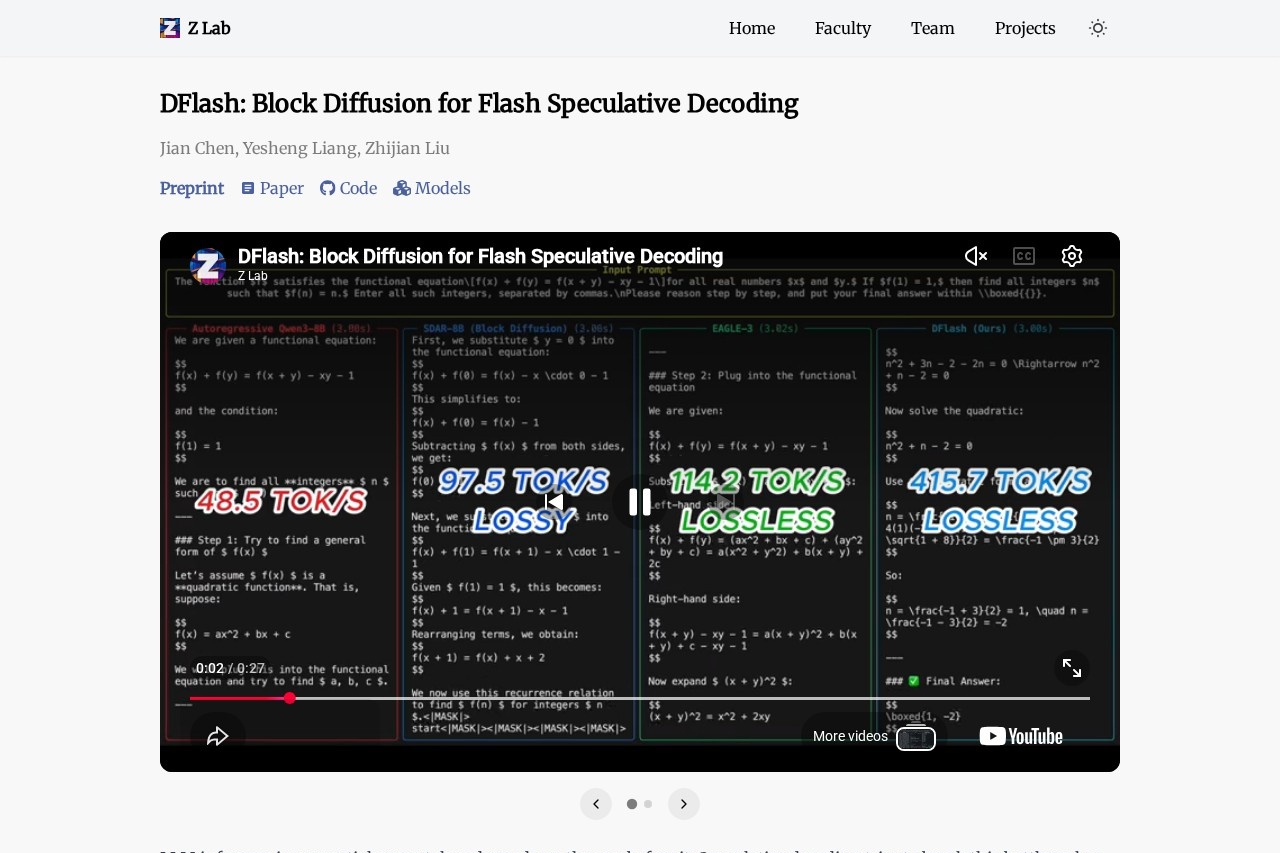
DFlash is a cutting-edge technology by Z Lab that accelerates large language model inference through block diffusion and speculative decoding, delivering up to 3x speedup without compromising quality.
Introduction
DFlash: Block Diffusion for Flash Speculative Decoding is a cutting-edge technology developed by Z Lab, designed to tackle the efficiency bottlenecks in large language model inference. Traditional autoregressive decoding methods deliver high accuracy, but generation speed is constrained by token-by-token computation, making it difficult to meet the demands of real-time applications. By combining a block diffusion mechanism with speculative decoding, DFlash significantly boosts inference throughput without compromising generation quality. This technology is especially well-suited for fast-response dialogue systems, content generation tools, and edge deployment scenarios, offering developers an efficient and scalable solution.
Key Features
- Block Diffusion Speculative Decoding: Uses a diffusion model to generate multiple candidate token blocks in parallel, paired with a lightweight verifier for rapid screening, substantially reducing the number of decoding steps.
- Low-Latency Inference: Leverages precomputation and cache optimization to cut single-inference latency down to 30%-50% of traditional methods.
- Seamless Integration: Supports mainstream deep learning frameworks such as PyTorch and TensorFlow, and provides a clean API interface for easy integration into existing workflows.
- Dynamic Resource Tuning: Automatically adjusts block size and parallelism based on hardware configuration to balance speed and memory usage.
Highlights
- High Efficiency: Compared to standard speculative decoding, DFlash's block diffusion strategy reduces redundant computation by roughly 40%, delivering 2-3x acceleration on the same hardware.
- Lossless Quality: Through progressive refinement in the diffusion process, generated text maintains coherence and accuracy on par with traditional autoregressive methods, and even performs better on certain tasks.
- Ease of Use: Comes with pretrained models and ready-to-run configuration examples, allowing quick deployment without deep knowledge of diffusion model internals.
- Scalability: Supports elastic scaling from a single GPU to multi-node clusters, adapting seamlessly to both cloud and on-premises environments.
Who It's For
AI researchers and engineers looking to explore new decoding paradigms and optimize large model inference performance; product developers who need to integrate real-time AI capabilities such as chatbots or code completion into their applications; edge computing practitioners deploying large models on resource-constrained devices while prioritizing low power consumption and fast response; and enterprise technology decision-makers evaluating options to reduce LLM serving costs and improve user experience.