
A native macOS inference server on MLX with paged SSD KV caching, reducing TTFT to under 5s. OpenAI & Anthropic compatible.
About
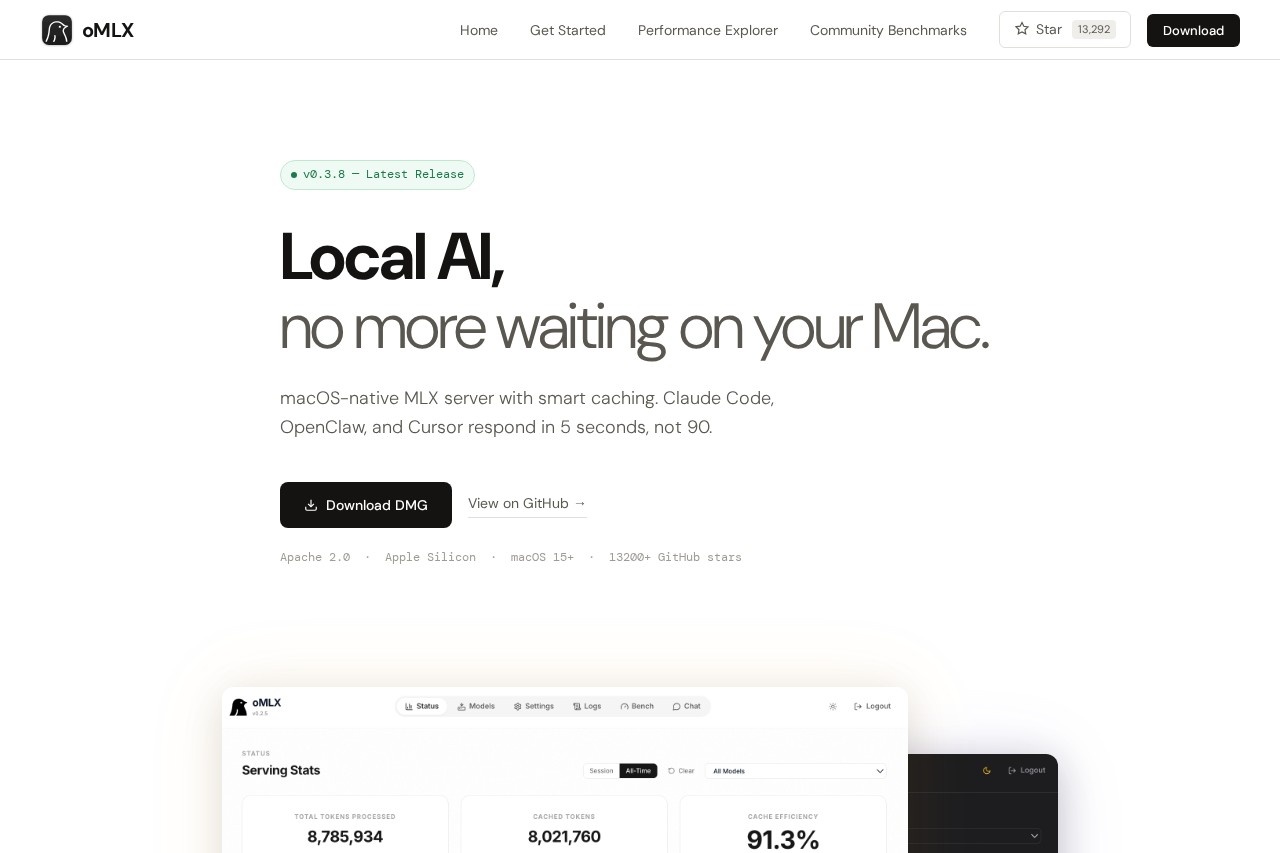
oMLX is a native inference server designed specifically for macOS, built on Apple's MLX framework to fully unlock the deep learning potential of Apple Silicon chips. Whether you're running large language models (LLMs) or building intelligent agent applications, oMLX delivers efficient, low-latency local inference. With its innovative Paged SSD KV caching technology, oMLX dramatically reduces the time-to-first-token (TTFT) for agent tasks from the traditional 30-90 seconds down to under 5 seconds, making local AI applications truly ready to use out of the box. Additionally, oMLX offers API interfaces compatible with both OpenAI and Anthropic, allowing developers to seamlessly migrate existing projects with minimal effort.
Key Features
Pricing & Fees
- Pricing: Not publicly listed on the pages we reviewed; check the official site for current plans.
- Open source license: oMLX is released under the Apache 2.0 license, with downloads available from the official site and GitHub.
- Platform availability: Runs natively on macOS (15+) on Apple Silicon; shipped as a signed, notarized menu bar app with auto-update.
- API access: Local inference server exposes OpenAI- and Anthropic-compatible endpoints, working drop-in with Claude Code, Cursor, and other OpenAI-compatible clients at no code change.
Who It's For
AI application developers who need to quickly build local LLM-powered tools (such as intelligent customer service, document analysis, or code generation) while keeping inference costs and latency under control. Privacy-conscious users in enterprise or individual settings who handle medical, legal, or financial data and require all inference to run locally to avoid cloud transmission risks. macOS performance enthusiasts who want to fully leverage Apple Silicon hardware to run mainstream open-source models (such as LLaMA, Mistral, and Phi) locally. Researchers and prototyping teams who need to rapidly validate multi-turn conversations or agent workflows without being constrained by cloud API rate limits or network instability.
Related Tutorials
View all →

Related Tools
View all → vLLM - Efficient LLM Serving vLLM is a high-throughput, memory-efficient inference and serving engine for LLMs. Optimize your AI deployment.
 9Router - Free AI Router Free AI routing with smart 3-tier fallback. Maximize subscriptions, auto-switch to cheap/free models. Never stop coding with Claude Code, Codex, Gemini CLI.
 OpenRouter OpenRouter is a unified, OpenAI-compatible API that gives developers pay-as-you-go access to 500+ AI models for text, image, video, and audio from 80+ providers.
 OmniRoute - Free AI Gateway for Multi-Provider LLMs Free, open-source AI router with auto-fallback. 236 providers, one endpoint, 95 MCP tools, 17 routing strategies, A2A protocol, auto-combo engine, semantic cache, memory & skills. Deploy anywhere.
 LangChain LangChain provides a comprehensive suite of products to support developers throughout their entire development workflow.